OpenAI Explains Storage Architecture for Scale Beyond a Billion Users
The engineering article turns the growth story into practical questions about capacity, reliability, and operations.
What happened?
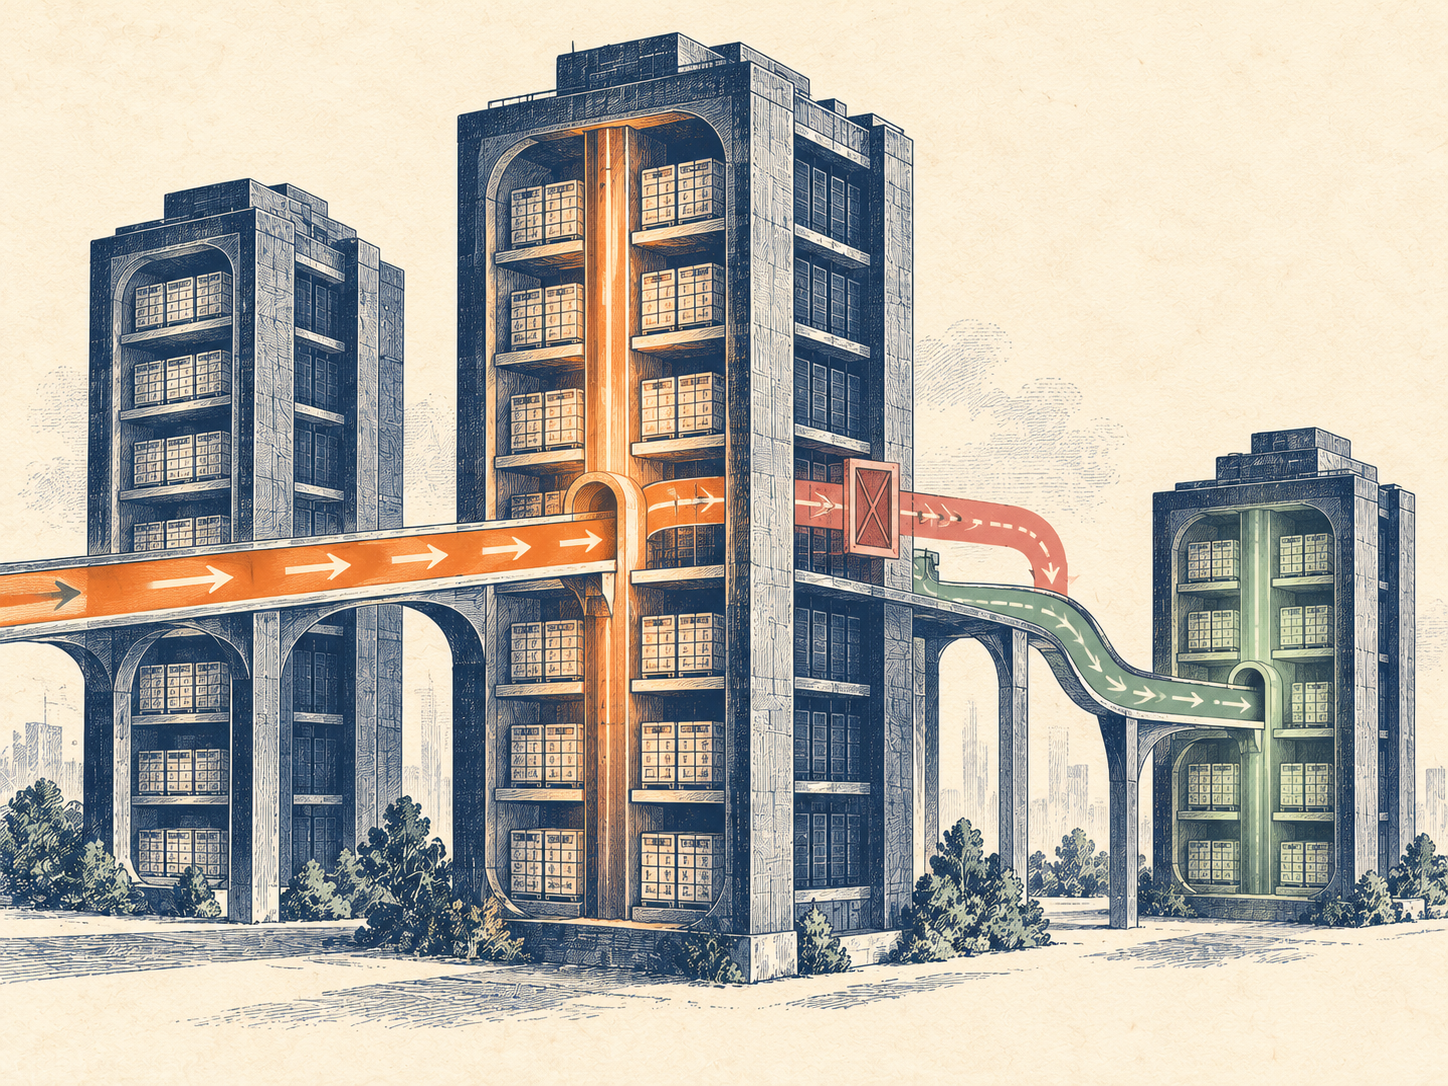
OpenAI published the second part of its explanation of how it scales storage for its services. The piece focuses on the engineering and operational decisions that allow the system to keep pace with increased usage.
Why does it matter?
Scaling AI products doesn't rely on models alone; data, storage, and retrieval layers can become the real bottleneck when usage reaches a global scale.
My perspective
I believe the executive lesson is to treat data infrastructure as part of the product itself, with clear capacity and recovery indicators before growth becomes an operational crisis.
Scope and availability
This is an engineering explanation of OpenAI's experience, not a ready-made recipe that can be transferred as-is to every organization.
Three executive questions
- Where do current capacity limits appear in our products?
- Are recovery plans tested under real pressure?
- What is the cost of retaining data versus the value of accessing it?